Build a story that can grow beyond the first page
Write · Illustrate · NarrateDevelop plot, characters, scenes, images, voice, and motion as one continuing creative workflow.
Stories designed as connected worlds
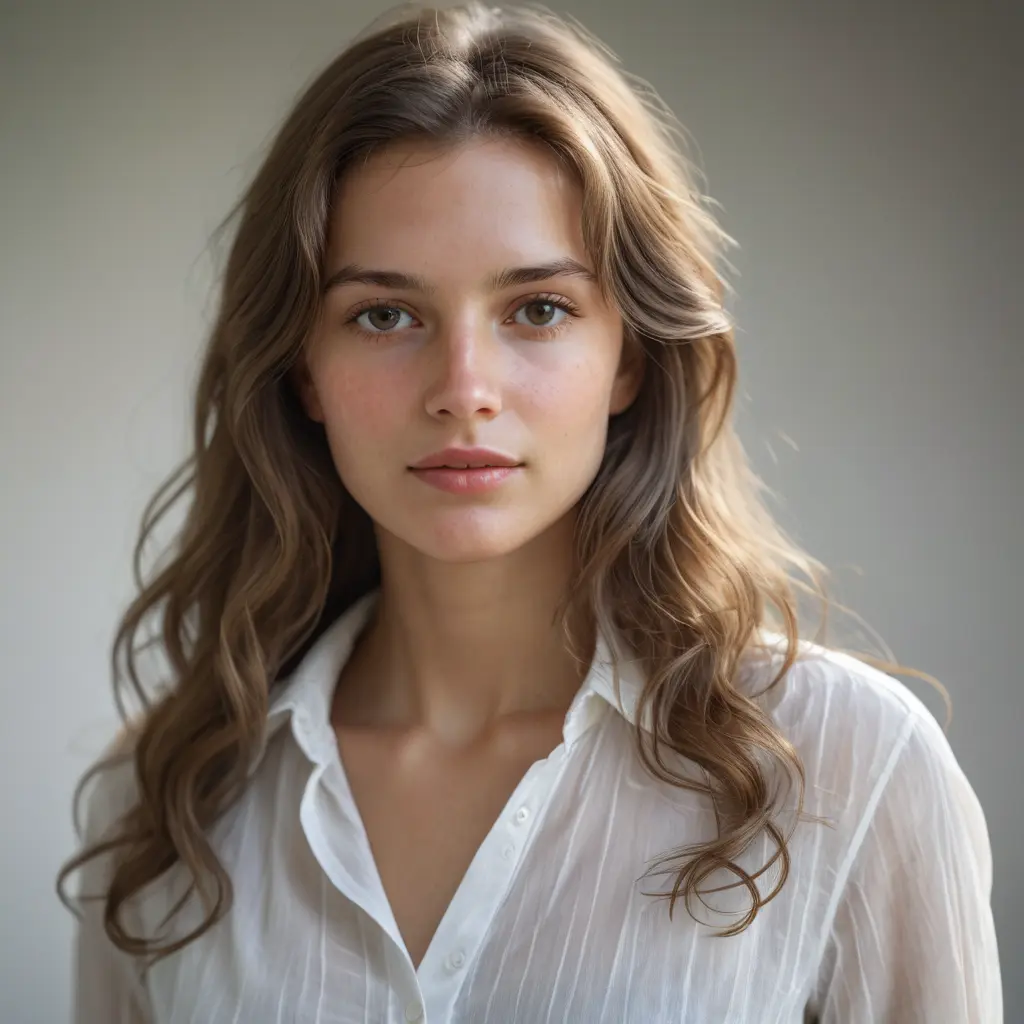
See exact generation prompt
A modern-day Snow White story set in Seoul, where a young artist rebuilds her career after her stepmother sabotages her portfolio.
Develop premise, character goals, scenes, pacing, and revision together.
Keep visual and narrative character facts available across scenes.
Generate scene images, narration, music, and video when the story needs them.
Turn a linear draft into a branching experience or game.
AI Story Models
 GizAIAuto
- Modalities
- text / image / file → text
- Capabilities
- Multimodal routing · Tools · Reasoning
- Routing
- Best fit per request
- Billing
- Selected model rate
Lets GizAI route each request to the most suitable chat model automatically.
 OpenAIGPT-5.6 Luna
- Modalities
- file / image / text / pdf → text
- Released
- Jul 9, 2026
- In / out price
- $0.1 in · $0.6 out / 1M
- Context
- 128K
- Max output
- 16.4K
- Capabilities
- Tools · Reasoning · Structured output
GPT-5.6 Luna is a fast, cost-efficient model in OpenAI's GPT-5.6 series. It is suited for high-volume, latency-sensitive tasks such as chat, classification, and lightweight agentic workflows, providing capable reasoning for...
OpenAIGPT-5.4 Nano- Modalities
- file / image / text / pdf → text
- Released
- Mar 17, 2026
- In / out price
- $0.1 in · $0.625 out / 1M
- Context
- 400K
- Max output
- 128K
- Capabilities
- Tools · Reasoning · Structured output
GPT-5.4 nano is the most lightweight and cost-efficient variant of the GPT-5.4 family, optimized for speed-critical and high-volume tasks. It supports text and image inputs and is designed for low-latency...
 xAIGrok 4.6
- Modalities
- text / image / file → text
- Released
- Aug 12, 2026
- In / out price
- $2 in · $6 out / 1M
- Context
- 500K
- Max output
- 450K
- Capabilities
- Tools · Reasoning · Structured output
Grok 4.6 is SpaceXAI's smartest model with frontier performance on coding, knowledge work, and STEM.
 DeepSeekDeepSeek V4 Flash 0731
- Modalities
- text / image → text
- Released
- Jul 31, 2026
- In / out price
- $0.04 in · $0.07 out / 1M
- Context
- 1M
- Max output
- 384K
- Capabilities
- Tools · Reasoning · Structured output
DeepSeek V4 Flash 0731 is a sparse mixture-of-experts model from DeepSeek, with 13B active parameters out of 284B total. This re-post-trained revision is suited for coding, reasoning, and agent workflows....
DeepSeekDeepSeek V4 Pro- Modalities
- text / image / file → text
- Released
- Apr 24, 2026
- In / out price
- $0.524 in · $1.05 out / 1M
- Context
- 1M
- Max output
- 384K
- Capabilities
- Tools · Reasoning · Structured output
DeepSeek V4 Pro is a large-scale Mixture-of-Experts model from DeepSeek with 1.6T total parameters and 49B activated parameters, supporting a 1M-token context window. It is designed for advanced reasoning, coding,...
 GoogleGemini 3.5 Flash-Lite
- Modalities
- text / image / video / file / audio / pdf → text
- Released
- Jul 21, 2026
- In / out price
- $0.15 in · $1.25 out / 1M
- Context
- 1.05M
- Max output
- 65.5K
- Capabilities
- Tools · Reasoning · Structured output
Gemini 3.5 Flash Lite is a high-efficiency model from Google with upgraded agentic capabilities. It is suited for subagents that execute focused tasks within complex, multi-agent workflows.
GoogleGemini 3.8 Flash- Modalities
- text / image / video / file / audio / pdf → text
- Released
- Sep 2, 2026
- In / out price
- $0.375 in · $1.88 out / 1M
- Context
- 1.05M
- Max output
- 65.5K
- Capabilities
- Tools · Reasoning · Structured output
Gemini 3.8 Flash is Google's most intelligent Flash model with significant gains from 3.7 Flash across software engineering, agentic tasks, and multi-step reasoning.
GoogleGemma 4 31B- Modalities
- image / text / video / pdf → text
- Released
- Apr 2, 2026
- In / out price
- $0.09 in · $0.34 out / 1M
- Context
- 262K
- Max output
- 16.4K
- Capabilities
- Tools · Reasoning · Structured output
Gemma 4 31B Instruct is Google DeepMind's 30.7B dense multimodal model supporting text and image input with text output. Features a 256K token context window, configurable thinking/reasoning mode, native function...
 Z.aiGLM 5.2
- Modalities
- text / image / file → text
- Released
- Jun 16, 2026
- In / out price
- $0.48 in · $1.51 out / 1M
- Context
- 1.05M
- Max output
- 182K
- Capabilities
- Tools · Reasoning · Structured output
GLM 5.2 is a large-scale reasoning model from Z.ai. It supports text input and output with a 1M-token context window, and is suited for long-horizon agent workflows, project-level software engineering,...
 MiniMaxMiniMax M3
- Modalities
- text / image / video / pdf / file → text
- Released
- May 31, 2026
- In / out price
- $0.23 in · $0.96 out / 1M
- Context
- 1.05M
- Max output
- 512K
- Capabilities
- Tools · Reasoning · Structured output
MiniMax-M3 is a multimodal foundation model from MiniMax. It supports text, image, and video inputs with text output, a 1M-token context window, and is suited for long-horizon agentic work, coding,...
Z.aiGLM 5.3 Flash- Modalities
- text / image / video / file → text
- Released
- Aug 26, 2026
- In / out price
- $0.075 in · $0.25 out / 1M
- Context
- 1.31M
- Max output
- 131K
- Capabilities
- Tools · Reasoning · Structured output
GLM-5.3-Flash is a native multimodal model from Z.ai. It is suited for efficient coding and long-horizon agent tasks. Its hybrid sparse and linear attention architecture maintains accurate long-context behavior while...
 Moonshot AIKimi K2.6
- Modalities
- text / image / video / file → text
- Released
- Apr 20, 2026
- In / out price
- $0.58 in · $2.44 out / 1M
- Context
- 262K
- Max output
- 8.19K
- Capabilities
- Tools · Reasoning · Structured output
Kimi K2.6 is Moonshot AI's next-generation multimodal model, designed for long-horizon coding, coding-driven UI/UX generation, and multi-agent orchestration. It handles complex end-to-end coding tasks across Python, Rust, and Go, and...
 AlibabaQwen3.8 Flash Next
- Modalities
- text / image / video / pdf / file → text
- Released
- Aug 26, 2026
- In / out price
- $0.15 in · $0.47 out / 1M
- Context
- 262K
- Max output
- 131K
- Capabilities
- Tools · Reasoning · Structured output
Qwen3.8 Flash is a multimodal reasoning model from Alibaba. It is suited for coding assistance, agentic workflows, visual understanding, document and codebase analysis, desktop interaction, chart analysis, and long-video analysis.
AlibabaQwen3.7 Plus- Modalities
- text / image / pdf / file → text
- Released
- Jun 3, 2026
- In / out price
- $0.32 in · $1.28 out / 1M
- Context
- 1M
- Max output
- 131K
- Capabilities
- Tools · Reasoning · Structured output
Qwen3.7-Plus is a cost-effective model in Alibaba's Qwen3.7 series. It supports text and image input with text output, building on the series' text capabilities with a comprehensive upgrade to its...
OpenAIGPT-6 Astra- Modalities
- file / image / text / pdf → text
- Released
- Sep 4, 2026
- In / out price
- $5 in · $25 out / 1M
- Context
- 1.05M
- Max output
- 128K
- Capabilities
- Tools · Reasoning · Structured output
GPT-6 Astra is OpenAI's flagship model for demanding end-to-end work. It is suited for advanced analysis, software engineering, deep research, scientific work, and document creation, with particular strengths in long-horizon...
OpenAIGPT-5.6 Terra- Modalities
- file / image / text / pdf → text
- Released
- Jul 9, 2026
- In / out price
- $1 in · $6 out / 1M
- Context
- 1.05M
- Max output
- 128K
- Capabilities
- Tools · Reasoning · Structured output
GPT-5.6 Terra is a balanced model in OpenAI's GPT-5.6 series, positioned between the flagship Sol tier and the cost-efficient Luna tier. It is suited for everyday coding, reasoning, and agentic...
OpenAIGPT-5.6 Sol- Modalities
- file / image / text / pdf → text
- Released
- Jul 9, 2026
- In / out price
- $1 in · $5 out / 1M
- Context
- 128K
- Max output
- 16.4K
- Capabilities
- Tools · Reasoning · Structured output
GPT-5.6 Sol is the flagship model in OpenAI's GPT-5.6 series. It is suited for complex reasoning, coding, and agentic workflows, and is particularly strong at command-line and multi-step coding tasks...
 AnthropicClaude Fable 5.1
- Modalities
- text / image / file / pdf → text
- Released
- Sep 1, 2026
- In / out price
- $10 in · $50 out / 1M
- Context
- 1M
- Max output
- 128K
- Capabilities
- Tools · Reasoning · Structured output
Claude Fable 5.1 improves on Claude Fable 5 across the board, with the biggest gains in agentic coding, long-running agentic workflows, and knowledge work: long code refactors, front-end and visual...
AnthropicClaude Sonnet 5- Modalities
- text / image / file / pdf → text
- Released
- Jun 30, 2026
- In / out price
- $2 in · $10 out / 1M
- Context
- 1M
- Max output
- 128K
- Capabilities
- Tools · Reasoning · Structured output
Sonnet 5 is Anthropic's most capable Sonnet-class model, with frontier performance across coding, agents, and professional work. It supports adaptive thinking with selectable reasoning effort levels (low, medium, high, max,...
Choose a story model by narrative workload
Short ideation, long manuscripts, visual references, multilingual prose, and tool-driven media production place different demands on the chat model.
 Auto
- Best for
- Starting a story without comparing models
- Why choose it
- Routes the request to a suitable available model while preserving the same media workflow.
- Watch for
- Select a fixed model when consistent behavior across a long project matters.
 DeepSeek V4 Flash 0731
- Best for
- Fast outlining, scene iteration, and structured revision
- Why choose it
- Useful for repeated planning, continuity checks, and compact creative feedback.
- Watch for
- Fast generation can default to familiar patterns; provide specific constraints and revise intentionally.
Kimi K2.6- Best for
- Long manuscripts, story bibles, and continuity synthesis
- Why choose it
- A long-context model is useful when many chapters, characters, and facts must remain available.
- Watch for
- Large context does not guarantee equal attention to every fact; keep a concise canonical story bible.
 Gemini 3.8 Flash
- Best for
- Visual references and multimodal story development
- Why choose it
- Useful when character or scene images need to inform written planning and revision.
- Watch for
- Visual interpretation and narrative inference should be checked against the actual reference.
 Qwen3.7 Plus
- Best for
- Multilingual stories and constrained structure
- Why choose it
- Supports cross-language drafting, structured outputs, and reasoning over narrative rules.
- Watch for
- Review cultural tone, idiom, names, and localized genre conventions with a fluent reader.
What an AI story generator cannot guarantee
Generic prompts can produce familiar plots, voices, and tropes. Add concrete character motives, setting rules, contradictions, and stylistic constraints.
Names, ages, relationships, locations, chronology, objects, and visual identity may change across long stories or generated media.
Use only authorized text, characters, images, and voices. Do not request imitation that creates avoidable copyright, likeness, or trademark risk.
A good story does not guarantee consistent illustrations, narration, music, or video. Review each modality against the story bible.
Children’s, educational, historical, health, and culturally specific stories need age, fact, bias, safety, and representation review.
Story examples
Browse real story examples made with GizAI.
How this page was reviewed
Written by GizAI Product Team · Reviewed by GizAI Model Operations · Updated 2026-07-16
GizAI publishes this AI story generator page about its own product. Model names, inputs, controls, access, and plan requirements come from the live GizAI catalog; examples and editorial guidance explain practical use without promising flawless output.
- Match the AI story generator default, offered models, and example inputs to active GizAI model contracts.
- Run the public form through model selection, example application, and the canonical Assistant handoff.
- Check examples for concrete audience, character, conflict, structure, output, and continuity direction.
- Verify one canonical URL, visible FAQs, structured data, internal links, desktop layout, and mobile layout.
AI story generator FAQ
Can the same character stay consistent?
Use a canonical character sheet with name, age, appearance, clothing, motives, relationships, speech patterns, and visual references. Consistency also depends on the selected image model and human review.
Can a story include images and voice?
Yes. Story workflows can continue into supported image, speech, music, and video models. Each generated asset has its own model contract and should be reviewed against the story bible.
Can I create an interactive story?
Yes. Define the player role, state, branch rules, consequences, win or end conditions, then continue into the game workflow.
What should a strong story prompt include?
State the audience, genre, premise, protagonist, desire, obstacle, setting rules, point of view, tone, length, structure, prohibited elements, and the exact next deliverable.
How do I continue a long story without contradictions?
Maintain a short story bible and timeline, summarize only approved canon after each chapter, identify unresolved threads, and ask for a continuity check before drafting the next scene.
Can I publish an AI-assisted story?
Publication suitability depends on your inputs, the amount of human authorship, rights, provider terms, and local law. Review originality, attribution, disclosure, likenesses, and contracts.
Can it write in multiple languages?
Yes with multilingual chat models, but literary tone, idiom, cultural references, names, and genre expectations should be reviewed by a fluent editor.
Which model is best for a novel?
Long-context models help with large manuscripts, while faster models help with iterative outlining and revision. No model replaces a maintained story bible, scene-level editing, and a final human manuscript review.